Spend and limits
Two places: the dashboard on the home screen and a screen of its own.
The dashboard on the home screen
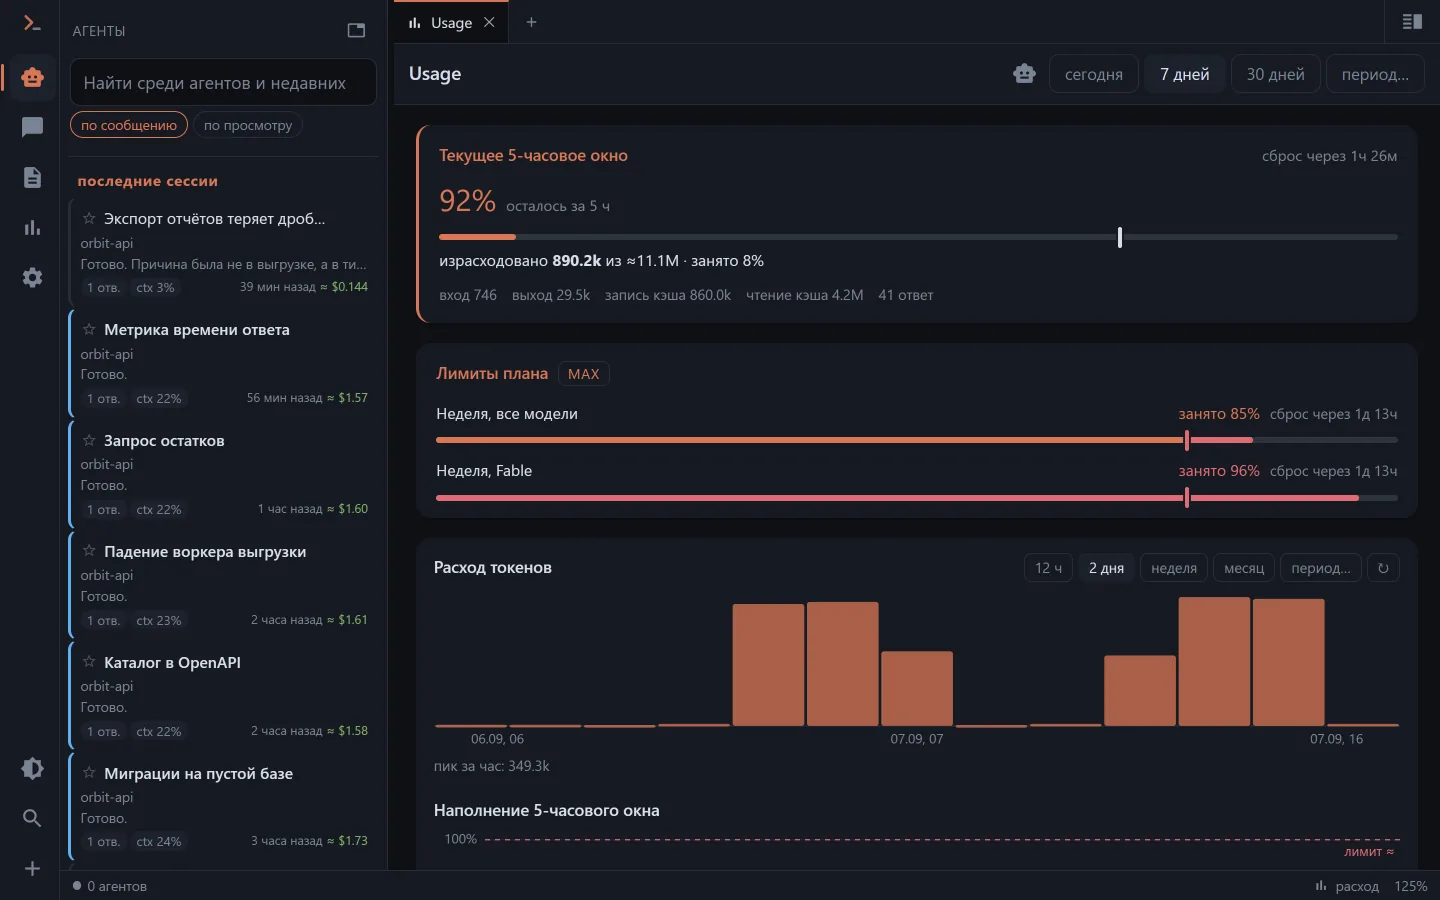
Hourly spend bars and the fill of the 5-hour window. That is usually enough to tell whether to start a big task now or wait.
The spend screen
- three windows as identical cards — the 5-hour window, the week across all models and the week for Fable: what is left in large type, a bar with the pace mark, "used X of ≈Y". If the plan did not report the 5-hour percentage, it is worked out from usage and the plan ceiling and marked
≈. The plan does not always report a separate Fable window; then the Fable card shows its share of the overall weekly window, also marked≈and explained. Until the plan answers, the weekly cards show the week's usage; - plan limits — the plan tier and any other windows the plan reports (Opus, Sonnet, third-party apps);
- this week's usage — bars by day, stacked by model (Fable, Opus, Sonnet, Haiku). The week starts at the plan's weekly reset, or covers the last 7 days if that is unknown. When the plan reports the weekly percentage, the total comes with an estimate of the whole week — overall and per model;
- breakdowns by day, model and project;
- a network traffic chart for the api itself, split by client.
The pace mark on the limit bars shows how much of the window's time has already passed. Spend to the left of the mark — you will fit; to the right — you are burning faster than the clock runs. That is more useful than a bare percentage: 60% in the first hour of a five-hour window and 60% in the fourth are different news.
A share of the window instead of a sum
On a subscription dollars take nothing off, and "≈ $2.40 for this chat" doesn't answer the only real question: whether to start the next task here. So the common badge row carries a ≈ 12% chip — the share of the five-hour window already eaten. It is on the chat, on the agent and in the app panel's rows; the API-price estimate and the tokens haven't gone anywhere — they are in the chip's tooltip and in the spend list's line.
A project gets the same measure summed across all its chats, and it deliberately has no 100% ceiling: a project accumulates over years and really does eat dozens of windows, so ≈ 2100% is not an error. If the plan's limit is unknown, the chip falls back to the old sum in dollars.
Where the window ceiling comes from
The plan doesn't say how many tokens the five-hour window holds — it only reports a percentage. The ceiling is computed by the server from your plan: it collects honest samples (the window is at least 3% full, and it is the same window as the plan's), brings them to a Pro unit, takes the median and multiplies it by the plan — Pro, Max 5× or Max 20×. Change the Max tier on the spend screen and the numbers are recomputed at once. Until there are samples of your own, a typical measurement for the plan is used, so chats show their share from the first minute.
The server remembers the plan, so the ceiling doesn't vanish after a restart or an update; a picked Max tier by itself means a Max subscription. If the plan isn't known yet (or no Max tier is picked), chats show a sum instead of an invented percentage.
There is no need to enter the limit by hand any more. The "5-hour window limit" card in the "Appearance" settings group shows the ceiling from your plan and where it came from; the "Own value" field remains in case your number is more accurate — then it wins. The window counter under the chat feed counts from the same ceiling.
A spending cap
You set a task from the phone and walked away — it helps to know the agent won't eat too much in a day. The "Agent" group of the settings has two thresholds in dollars for the last day (a sliding 24 hours, not a calendar day), both optional:
- a warning — a plate with the sum appears above the new-chat field;
- a stop — the server won't start a new chat, including from the Telegram bot. Running chats keep going and can be continued: cutting work off mid-reply over a sum is worse than paying for its tail.
The sum is counted from the same transcripts at API prices. On a subscription it is an estimate, on an API key it is the real bill; your own model servers cost nothing. Only the owner sets the thresholds. A key scoped to projects doesn't see the sum: it is the whole machine's money, not its projects'.
In the chat
The token line under the composer shows the spend rate when tapped. Under a message about a limit you have hit there is a countdown to the reset — 5 hours, a week, and the weekly windows per model.
Right next to it is the context window, but that is about something else: context is how much fits into one conversation, a limit is how much you have left on the plan.
Where the numbers come from
From the same transcripts: the api parses the records and keeps an index in SQLite (clauder.db) next to the sessions directory.
That gives two quirks worth knowing about:
- The first visit after a long break may lag behind. The index catches up by scanning and runs into a budget; a repeated request picks up the rest.
- A broken index is cured by deleting the file.
clauder.dbcan be deleted — it will be rebuilt. Favourites, your own titles and "read" marks go with it, though: they live in the same place.
The limit warning
A separate toggle in notifications sends a warning at 95% — both for the 5-hour window and for the weekly ones. It is about the whole machine, not only about your chats in Clauder.